Agent swarms are getting popular for faster work, but the big fear is simple.
Who knows what the agents are doing, and how do you catch mistakes before code ships?
That’s why security-first agent swarms is becoming a real focus, not just a nice idea.
In this article, you’ll learn how new tools like AgentGraph 2.0 add a visual debugging view for multi-agent communication, how Claude Opus 5.5 is pushing large code migration tasks, and how automated code review systems can help you keep control when you run thousands of steps in parallel.
You’ll also get practical ideas you can use to build safer agent workflows, with a checklist you can follow the next time you run an agent swarm.
And if you care about agent reliability, this topic is worth your time.
What “security-first agent swarms” really means
When people hear “agent swarm,” they often imagine a bunch of bots doing work at the speed of light.
Cool, right.
But security-first agent swarms focuses on something less flashy.
It focuses on visibility and control.
Here are the key goals in plain terms:
-
You can see what each agent is doing.
Not just the final output. -
You can trace decisions and tool calls.
So you can explain how a result was produced. -
You can stop bad actions early.
If something looks off, the system should fail safely. -
You can review code automatically, then validate it.
Especially when agents generate or modify lots of files.
This matters more when you scale up.
For example, Cursor’s “Projects” feature uses a coordinator agent to plan work and delegate to thousands of parallel sub-agents.
If you run that kind of parallel system without guardrails, debugging turns into guesswork.
Source from search results: Cursor “Projects” with a Coordinator Agent delegate to thousands of parallel sub-agents appears as a recent release summary in the provided results (cursor.com redirect).
So the question becomes: how do you get the visibility that keeps the swarm safe?
AgentGraph 2.0: visual debugging for large agent communication
One of the most promising ideas in this space is improving debugging for swarm workflows.
If you have 20 agents talking, you can read logs.
If you have 200 or 500 concurrent agents, you need something else.
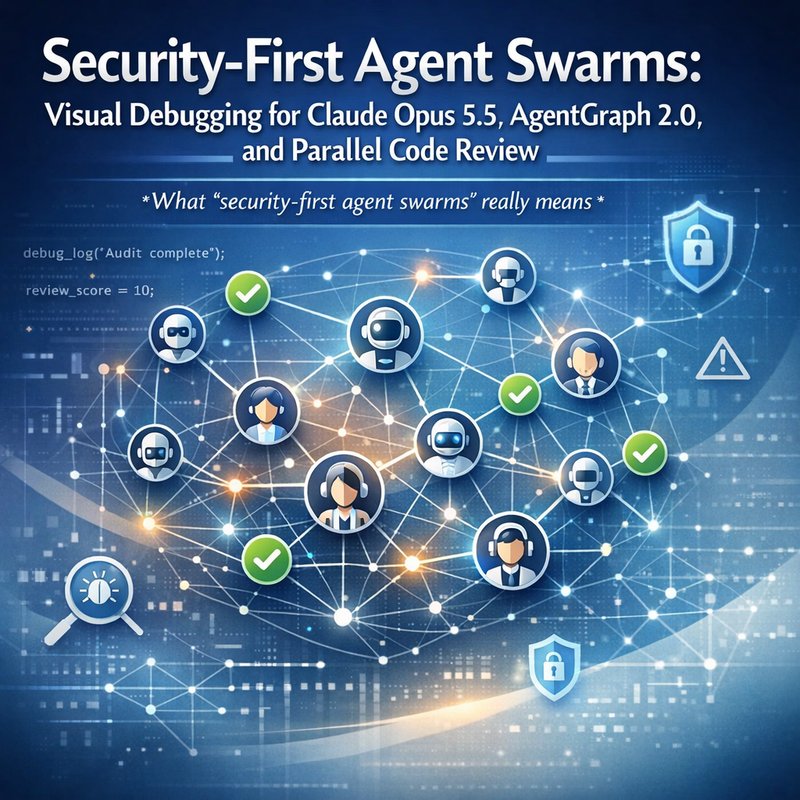
AgentGraph 2.0 is described in the search results as an open-source update with a visual debugging interface that can map communication flows for up to 500 concurrent agents.
It also mentions templates for “consensus-based decision making” and awareness across 15 linked repositories.
Source from search results: “AgentGraph 2.0” visual debugging interface + up to 500 concurrent agents described on skillsllm.com (provided redirect link).
Let’s translate that into why it helps with security-first agent swarms.
Why visual debugging beats log hunting
Logs are helpful but they hide the relationships between agents.
A swarm isn’t just one chain of steps.
It’s a network of messages.
A visual view helps you spot issues like:
- Looping behavior where agents keep re-triggering each other
- Conflicting recommendations where sub-agents argue and no one resolves it
- Unexpected tool usage like an agent calling an action you never asked for
- Long-range influence where early decisions have strange downstream effects
When you’re using security-first agent swarms ideas, visibility is step one.
Because if you can’t see the path, you can’t trust the result.
Consensus-based decisions for safer parallel work
The search results mention that AgentGraph 2.0 includes new templates for “consensus-based decision making” in agent swarms.
That’s a big deal, because it changes how you validate outputs.
Instead of trusting a single agent to decide, you can:
- Ask multiple agents to produce plans or patches
- Compare their reasoning
- Use a tie-break method
- Keep the most consistent option, then require validation
This is not perfect.
But it’s a move toward safer systems, because errors become harder to hide.
Practical setup you can copy
If you want to use the same idea without learning every detail of AgentGraph, start smaller:
- Pick a single risky action (like editing many files or running migrations).
- Run at least two independent agents to propose changes.
- Use a consensus check (even a simple diff comparison).
- Allow tool execution only after review.
That workflow is the same spirit as security-first agent swarms.
You’re adding checkpoints before actions become irreversible.
If you are also running other automation, it helps to connect your process.
Neura can route tasks to the right agent types (router agents that route based on user intent).
You can explore that at https://meetneura.ai/products and connect your workflow design to how you want outputs reviewed.
(That’s not saying “Neura replaces debugging tools.”)
It’s just a reminder: security-first agent swarms is about system design, not only model choice.
Claude Opus 5.5 and why big code moves need stricter guardrails
The search results mention Claude Opus 5.5 as released September 22, 2026, and describe an example where a developer used Opus 5.5 to complete a 680,000-line code migration in under 24 hours.
Source from search results: anthropic.com entry summary for Claude Opus 5.5 release and benchmark-like story (provided redirect link).
That’s impressive.
But here’s the security-first angle.
When AI models can move huge codebases quickly, mistakes can also scale quickly.
A small misunderstanding can become a massive refactor with broken logic, security bugs, or inconsistent behavior.
So the safest approach is not “run it and hope.”
The safer approach is: “run it with review paths that don’t rely on vibes.”
Add code review that can’t be ignored
The search results also mention a YouTube item that says it uses a Software Delivery Knowledge Graph to prioritize and automatically review agent-generated code.
Source from search results: youtube.com redirect summary mentioning Software Delivery Knowledge Graph prioritization and automated review steps.
When you combine that idea with big migration speedups, you get a key pattern:
- Agents propose changes fast.
- Automated systems review what matters first.
- You validate with tests and checks.
A security-first agent swarm treats review as part of the main workflow, not an afterthought.
A realistic counterargument
Some people will say: “If the model is smart enough, review is slower than the benefit.”
Fair point.
But in real teams, code review is not only about correctness.
It’s also about:
- consistency with style and architecture
- security-sensitive updates
- safe migration sequencing
- making sure no one can hide behind “the model did it”
So even if review adds time, it can reduce the worst-case time loss when something breaks later.
Parallel execution at scale: what to watch for
Security-first agent swarms is hard mostly because parallel systems are chaotic.
Even when everything is technically “working,” it can still be unsafe.
Here are common failure modes when you delegate to many agents:
1) Agents act on incomplete info
One agent might start editing while another agent is still gathering context.
Then file changes can conflict.
Visual debugging helps you see time ordering and message flow.
But even without tools, you can mitigate by enforcing phases:
- research phase
- plan phase
- patch phase
- review phase
2) Tool calls happen before checks
If your swarm can call tools immediately, an agent might run commands that are hard to undo.
The swarm should be able to “think” without “acting” until validation passes.
3) “Consensus” can still fail
Consensus can reduce random mistakes, but it can also create a false sense of safety.
If all agents share the same wrong assumption (for example, the same outdated docs), consensus just agrees faster.
The fix is to diversify sources:
- different agents use different prompts
- different agents read different parts of the repo
- different agents rely on different evidence inputs
A simple security-first blueprint you can implement today
You might be thinking: “Okay, but what do I do next week?”
Here’s a straightforward blueprint that fits most agent swarm setups, even if you are not using AgentGraph 2.0 directly.
Step 1: Separate “plan” from “execute”
Don’t let agents jump straight to file edits or commands.
In your system:
- Agents generate a plan.
- Another step verifies the plan (or compares multiple plans).
- Only then you allow execution.
This single change can dramatically improve safety.
Step 2: Enforce an approval gate for dangerous actions
Define high-risk actions, for example:
- touching security-related files
- changing auth flows
- updating dependencies
- running migrations
- changing build or deployment scripts
In security-first agent swarms, those actions should require a gate.
Even basic checks help:
- “Did the patch only touch expected directories?”
- “Did it add or remove permissions?”
- “Does the change pass unit tests?”
Step 3: Use a visual or trace-based debugging view
If you can use AgentGraph 2.0’s visual debugging interface, go for it.
The value is that you can see how messages move between agents.
Source from search results: AgentGraph 2.0 visual debugging for up to 500 concurrent agents.
If you cannot use a specific tool right now, you can mimic the idea:
- attach a trace ID to each agent message
- log tool calls as structured events
- store a timeline of plan and execution steps
This is the “poor person” version of visual debugging.
Still useful.
Step 4: Add automated prioritization for review
The YouTube result mentioned a Software Delivery Knowledge Graph that prioritizes and automatically reviews agent-generated code.
The pattern you want is:
- identify the files most likely to hide high risk
- focus review on those first
- do spot checks elsewhere
This keeps review manageable while still staying safe.
Step 5: Run tests with an “agent diff mindset”
Don’t only test the final output.
Also test:
- the diff summary
- migration steps
- critical paths
Security-first agent swarms assumes that “large changes” can cause subtle breakage.
So treat each swarm patch as a real engineering change, not an experiment.
Where Neura fits in a safer workflow design
You might not use Neura for every low-level swarm debug step.
That’s fine.
Neura’s value is connecting tasks across tools and routing requests to the right agent types.
For example, Neura includes a Router Agent concept that routes based on user intent, and it supports many capabilities like document analysis, image analysis, transcription, and more through its ecosystem.
You can explore Neura’s product overview here: https://meetneura.ai/products
And you can browse the main app links at https://meetneura.ai.
Where this helps with security-first agent swarms is process control:
- you can centralize how tasks get routed
- you can standardize what evidence outputs must be attached
- you can standardize which steps require human review
Again, visual debugging tools are still needed.
But an orchestrator helps you keep the process consistent.
Also, if you want to see real examples of how Neura is used in projects, check the case studies section: https://blog.meetneura.ai/#case-studies
A checklist for security-first agent swarms before you ship
Here’s a quick checklist you can use the next time you run a swarm.
Visibility
- Can you trace which agent made which decision?
- Do you have a timeline of plan and execution events?
- Do you know which repositories were touched?
This is where AgentGraph-like visual debugging shines for security-first agent swarms.
Action safety
- Are file edits and tool calls blocked until the plan is approved?
- Are dangerous actions behind an approval gate?
- Can you roll back?
Code review
- Is there automated review that prioritizes risky changes?
- Do you run tests that match the change type?
- Do you review diffs, not only final results?
Parallel sanity
- Do you prevent agents from editing while others are still researching?
- Do you detect conflicting patches?
- Do you force a final reconciliation step?
If you do these, you’ll catch more issues early.
And early is cheaper.
Conclusion: Faster swarms, safer shipping
Security-first agent swarms isn’t about slowing down AI work.
It’s about controlling it.
When models start moving huge codebases like the Claude Opus 5.5 example described in the search results, you can’t rely on speed alone.
You need traceability, review gates, and debugging that makes sense when many agents run at the same time.
Tools like AgentGraph 2.0 point in the right direction because visual debugging helps you see the network behavior, not just the final output.
Source from search results: AgentGraph 2.0 with visual debugging for up to 500 concurrent agents.
Meanwhile, automated code review systems that use knowledge graphs and prioritization ideas help keep review realistic when agent output is massive.
Source from search results: YouTube entry mentioning Software Delivery Knowledge Graph prioritizing and automatically reviewing agent-generated code.
The bottom line?
Run the swarm.
But make sure you can answer, clearly, “Who did what, why, and what changed?”